An open-loop trajectory specifies controls from an initial state to a final time. During execution, the control depends only on the clock, reading precomputed values or interpolating between them. The MPPI examples already used a different execution rule: apply one action, observe the new state, and update the remaining plan. Receding-horizon control applies this rule to any suitable finite-horizon optimizer, including the transcription methods developed in the preceding chapters.
Real systems face modeling errors, external disturbances, and measurement noise that accumulate over time. A precomputed trajectory becomes increasingly irrelevant as these perturbations push the actual system state away from the predicted path. The solution is to incorporate feedback, making control decisions that respond to the current state rather than blindly following a predetermined schedule. While dynamic programming provides the theoretical framework for deriving feedback policies through value functions and Bellman equations, there exists a more direct approach that leverages the trajectory optimization methods already developed.
Can the finite-horizon planner itself become a feedback controller by solving again whenever a new state is measured?
Learning Goals
After working through the derivations and the balancing example, you should be able to:
Turn a finite-horizon optimal-control problem into a state-feedback law by replanning, and state the feedback law and its domain precisely.
Explain why a short horizon without terminal ingredients can leave an unstable system uncontrolled, stall it near a constraint, or lose feasibility.
Prove recursive feasibility and closed-loop convergence from a terminal cost, a terminal set, and a local controller, using the shifted candidate sequence.
Construct a quadratic terminal cost and an ellipsoidal terminal set for a linear system with box constraints, and check both numerically.
Decide when the finite-horizon value is a lower bound, an upper bound, or neither, for the infinite-horizon value.
Prerequisites
The chapter uses the finite-horizon optimal-control formulation, the transcription methods that turn it into a nonlinear program, and the receding-horizon execution used by MPPI. The worked example solves small convex quadratic programs; only the facts that such programs have a unique solution and can be solved reliably are needed. Dynamic programming and the linear-quadratic regulator are not required. Where the example uses an LQR gain, the property it relies on is derived here.
Closing the Loop by Replanning
Which action from each finite-horizon solution should be applied before the state is measured and the horizon is shifted forward?
Model Predictive Control creates a feedback controller by repeatedly solving trajectory optimization problems. Rather than computing a single trajectory for the entire task duration, MPC solves a finite-horizon problem at each time step, starting from the current measured state. The controller then applies only the first control action from this solution before repeating the entire process. This strategy transforms any trajectory optimization method into a feedback controller.
The battery example in Model Interfaces used a transparent current governor: it tested a local voltage and thermal envelope after updating one resistance parameter. MPC retains that structured model but optimizes an entire future current sequence and repeats the optimization as measurements arrive.
The Receding Horizon Principle
The defining characteristic of MPC is its receding horizon strategy. At each time step, the controller solves an optimization problem looking a fixed duration into the future, but this prediction window constantly moves forward in time. The horizon “recedes” because it always starts from the current time and extends forward by the same amount.
Consider the discrete-time optimal control problem in Bolza form:
This is the Bolza problem of Finite-Horizon Optimal Control Problems, with its index counted from the current time rather than from the start of the task. If the state is measured at time , then is that measurement, is the state predicted for time , and the controls span the prediction horizon, as in the MPPI algorithm. For a time-varying task, , , and are the stage cost, dynamics, and constraints of time . The terminal cost is charged at the end of the prediction horizon, not at the end of the task.
At time step , this problem optimizes over the interval . At the next time step , the horizon shifts to . What makes this work is that only the first control from each optimization is applied. The remaining controls are discarded, though they may initialize the next optimization through warm-starting.
This receding horizon principle enables feedback without computing an explicit policy. By constantly updating predictions based on current measurements, MPC naturally corrects for disturbances and model errors. The apparent waste of computing but not using most of the trajectory is actually the mechanism that provides robustness.
A Balancing Example
Balancing a stick upright on a fingertip shows what replanning buys. The upright position is an equilibrium, but a small tilt grows on its own, so a precomputed command sequence that is slightly wrong does not stay slightly wrong. Linearized about the upright position, the angle obeys
where is the stick length and is the angular acceleration commanded through the fingertip. With m/s and m, a tilt grows by a factor about every s. We sample the model exactly under a zero-order hold with period s, which gives a linear model with . The command is limited to rad/s, and the angle must stay within rad. The stage cost is quadratic,
Each MPC subproblem is therefore a convex quadratic program in the commands and predicted states. The terminal cost and the terminal set used in this section are constructed in Constructing Terminal Ingredients. For now, treat them as given.
The experiment starts from : tilted and falling further. A plan with horizon (two seconds) is computed once from the nominal model. Two executions of that plan are then compared on a plant whose stick is 15% shorter than the model assumes, and which receives a tap on its angular rate of 0.5 rad/s at s. The first execution applies the 40 planned commands open loop. The second solves the same problem again from every measured state and applies only the first command.
Before looking at the result, predict which effect hurts the open-loop execution first: the shorter stick or the tap.
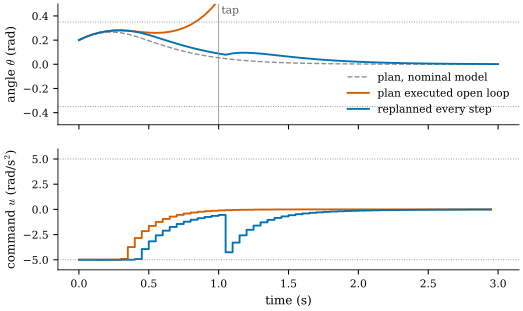
Figure 1:Executing one plan open loop against replanning at every step, on a plant whose stick is 15% shorter than the model. The dashed curve is the plan applied to the nominal model. Dotted lines mark the angle and command limits. The open-loop execution leaves the angle limit at s, before the tap. Replanning saturates the command during the first 0.4 s, absorbs the tap, and keeps rad.
The model error alone defeats the open-loop plan. The shorter stick falls faster than predicted, the planned commands are too small to catch it, and the angle leaves its limit at s, before the tap arrives. The open-loop execution never measures the state, so it cannot detect the error. The replanned controller solves the same optimization with the same wrong model, but each new solve starts from the measured state, so the accumulated prediction error is corrected one step at a time. Every one of its 60 subproblems is feasible, and the tap appears only as a second burst of command. Replanning does not repair the model. It limits how long a model error can act before it is measured.
The Controller Defined by Replanning
For a time-invariant problem, such as regulation of the stick, the subproblem depends on the time only through its initial state. Write for the first optimal command when the subproblem starts from . Replanning then executes the state-feedback law
The law is defined only where the subproblem has a solution. Call this set the feasible set : the states from which some admissible command sequence of length satisfies every constraint and ends in the terminal set. The law is never written down. It is evaluated one state at a time by an optimizer. The parametric controllers chapter studies the map as an object in its own right. For linear dynamics, quadratic costs, and polyhedral constraints, it is a continuous piecewise affine function of the state Bemporad et al. (2002).
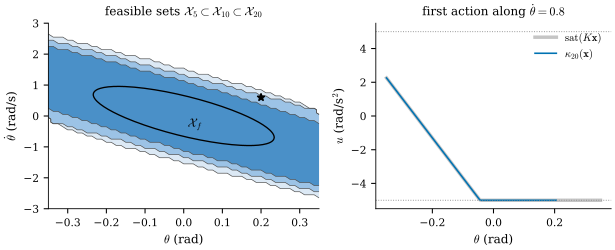
Figure 2:Left: feasible sets of the stick controller with terminal cost and terminal set, for (darkest), 10, and 20 (lightest), on a grid over the angle limits. The ellipse is the terminal set and the star is the initial state of Figure 1. Right: the first action along the line rad/s, with the saturated LQR law in grey. The MPC curve stops at rad, where the subproblem becomes infeasible.
Figure 2 shows both objects for the stick. The feasible sets are nested, : a longer horizon allows more steps to reach the terminal ellipse, so more initial states qualify. On the grid they cover 35%, 43%, and 49% of the plotted rectangle. The initial state lies outside the terminal ellipse, and nine steps are the fewest that reach it. Outside the shaded bands the stick is falling too fast in the direction of its tilt to be caught by commands of at most 5 rad/s without violating the angle limit.
The right panel contains a lesson specific to this small example. Wherever the subproblem is feasible, agrees with the saturated linear law to within rad/s, where is the LQR gain from which the terminal cost is built. For a two-dimensional state with one input, the active constraint along optimal paths is usually the input bound at the first step, and the optimizer rediscovers saturation. The optimizer adds two things that the saturated law lacks. First, it reports a state outside as infeasible instead of returning a command that cannot succeed. Second, the stability argument below comes with it. With more states, more inputs, or state constraints that become active along the way, the optimizer’s law departs from any saturated linear law.
Warm starting fits naturally here. Consecutive states are close, so the shifted previous solution is a good initial guess for the next solve. The proof of stability below uses almost the same shifted sequence, with the last entry chosen more carefully.
Horizon Selection and Problem Formulation
The choice of prediction horizon depends on the control objective. We distinguish between three cases, each requiring different mathematical formulations.
Infinite-Horizon Regulation
For stabilization problems where the system must operate indefinitely around an equilibrium, the dynamics, constraints, and stage cost are usually time-invariant, so we drop their index: , , and . The true objective is:
Since this cannot be solved directly, MPC approximates it with:
The terminal cost approximates , the cost-to-go beyond the horizon. The terminal constraint ensures the state reaches a region where a known stabilizing controller exists. Without these terminal ingredients, the finite-horizon approximation may produce unstable behavior, as the controller ignores consequences beyond the horizon.
Finite-Duration Tasks
For a task ending at time , the true objective from the current time is the remaining part of the Bolza objective, written in absolute time:
The MPC formulation must adapt as time progresses. While the end of the task lies beyond the prediction horizon, the subproblem keeps the surrogate terminal cost . Once , the horizon shrinks to the remaining steps:
In the second case, is the prediction of the final state , so the task’s own terminal cost applies. As the task approaches completion, the horizon shrinks and the terminal cost switches from the approximation to the true final cost . This prevents the controller from optimizing beyond task completion, which would produce meaningless or aggressive control actions.
Periodic Tasks
Some systems operate on repeating cycles where the optimal behavior depends on the time of day, week, or season. Consider a commercial building where heating costs are higher at night, electricity prices vary hourly, and occupancy patterns repeat daily. The MPC controller must account for these periodic patterns while planning over a finite horizon.
For tasks with period , such as daily building operations, the formulation accounts for transitions across period boundaries:
The stage cost changes with the phase of the predicted time within the period. Constraints may similarly depend on the phase, reflecting different operational requirements at different times.
The MPC Algorithm
The complete MPC procedure implements the receding horizon principle through repeated optimization:
Successive Linearization and Quadratic Approximations
Any solver that improves one finite-horizon plan by successive approximation can be used inside MPC: solve from the newly observed state, execute the first action, and repeat. The iLQR and DDP chapter, after dynamic programming, develops one such solver. Its backward-pass feedback gains and the outer decision to replan are distinct operations.
For many regulation and tracking problems, the nonlinear dynamics and costs we encounter can be approximated locally by linear and quadratic functions. The basic idea is to linearize the system around the current operating point and approximate the cost with a quadratic form. This reduces each MPC subproblem to a quadratic program (QP), which can be solved reliably and very quickly using standard solvers.
Suppose the true dynamics are nonlinear,
Around a nominal trajectory , we take a first-order expansion:
with Jacobians
Similarly, if the stage cost is nonlinear,
we approximate it quadratically near the nominal point:
with positive semidefinite weighting matrices and , where .
The resulting MPC subproblem has the form
where captures the local affine offset. The terminal weight plays the role of the terminal cost .
Because the dynamics are now linear and the cost quadratic, this optimization problem is a convex quadratic program. Quadratic programs are attractive in practice: they can be solved at kilohertz rates with mature numerical methods, making them the backbone of many real-time MPC implementations.
At each MPC step, the controller updates its linearization around the new operating point, constructs the local QP, and solves it. The process repeats, with the linear model and quadratic cost refreshed at every reoptimization. Despite the approximation, this yields a closed-loop controller that inherits the fast computation of QPs while retaining the ability to track trajectories of the underlying nonlinear system.
Theoretical Guarantees
Repeated optimization creates feedback, but which terminal ingredients make feasibility persist and the closed-loop state converge?
The finite-horizon approximation in MPC brings a new challenge: the controller cannot see consequences beyond the horizon. Without proper design, this myopia can destabilize even simple systems. The solution is to carefully encode information about the infinite-horizon problem into the finite-horizon optimization through its terminal conditions.
Before diving into the mathematics, we should first establish what “stability” means and which tasks these theoretical guarantees address, as the notion of stability varies significantly across different control objectives.
Stability Notions Across Control Tasks
The terminal conditions provide different types of guarantees depending on the control objective. For regulation problems, where the task is to drive the state to a fixed equilibrium (often shifted to the origin), the stability guarantee is asymptotic stability: starting sufficiently close to the equilibrium, the closed-loop state satisfies as while constraints remain satisfied throughout the trajectory (recursive feasibility). This requires the stage cost to be positive definite in the deviation from equilibrium.
When tracking a constant setpoint, the task becomes following a constant reference that solves the steady-state equations. This problem is handled by working in error coordinates and , transforming the tracking problem into a regulation problem for the error system. The stability guarantee becomes asymptotic tracking, meaning , again with recursive feasibility.
The terminal conditions we discuss below primarily address regulation and constant reference tracking. Time-varying tracking and economic MPC require additional techniques such as tube MPC and dissipativity theory.
What Goes Wrong Without Terminal Ingredients
Remove the terminal cost and the terminal set from the stick controller and keep everything else. Figure 3 shows the closed loop from the same initial state for several horizons, on the exact model and without disturbances.
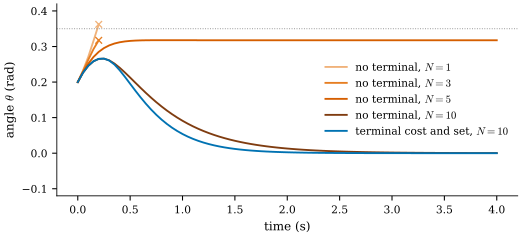
Figure 3:Closed-loop angle without terminal ingredients for (orange shades), and with terminal cost and set for (blue), on the exact model. A cross marks the first infeasible subproblem. With the stick settles at rad and stays there.
The failures differ in kind, and each one has a clear cause.
With , the objective is , and the next state does not enter it. Since is fixed, the minimizer is the cheapest command, , unless a constraint on forces more. The controller does nothing until the angle limit is about to be crossed, and by then no admissible command can prevent it: the subproblem at step 3 is infeasible.
With , the horizon covers 0.15 s, less than half the time the tilt needs to grow by a factor . Within that window, pushing the stick back costs command effort and returns little angle cost, so the plan does only what is needed to keep the predicted angle under its limit. The subproblem again becomes infeasible at step 3.
With , every subproblem is feasible, but the closed loop converges to rad, not to the upright position. There, each plan holds the stick with a constant command and keeps the predicted angle just inside the limit at the end of the horizon. The replanning law has acquired a second equilibrium. Convergence to the target is therefore not implied by feasibility.
With , the horizon is long enough, and the stick returns upright. Its closed-loop cost is 20.83, against 20.15 with terminal ingredients. The remaining gap is the price of a horizon that sees only part of the recovery.
A long enough horizon eventually stabilizes the system without any terminal ingredients, and there is a theory that quantifies “long enough” Grüne & Pannek (2017). The required length depends on the system and the initial state, and nothing in the subproblem reports when it is too short. The terminal ingredients make a different trade. They give a certificate that holds for every horizon, at the cost of a smaller feasible set: with the terminal set, the same initial state is infeasible for every .
MPC with Stability Guarantees
To provide theoretical guarantees, the finite-horizon MPC problem is augmented with three interconnected components. The terminal cost approximates the cost-to-go beyond the horizon, providing a surrogate for the infinite-horizon tail that cannot be explicitly optimized. The terminal constraint set defines a region where we have local knowledge of how to stabilize the system. Finally, the terminal controller is a local feedback policy that stabilizes the system within .
These components must satisfy specific compatibility conditions to provide theoretical guarantees. The statement below is for regulation to the origin with time-invariant dynamics , stage cost , and constraints , which include the state and input bounds. It follows Mayne et al. (2000).
Asymptotic stability, in the sense of a Lyapunov function, also needs to be bounded above by a multiple of near the origin. This holds, for example, when is quadratic and the origin lies in the interior of Rawlings et al. (2017). The three properties listed are the ones a practitioner relies on, and they follow from one construction.
The proof never uses optimality of the plan beyond the first step. It compares the new optimum with one feasible candidate. Two practical consequences follow. First, the guarantees survive an inexact solver as long as each returned plan is feasible and costs no more than the shifted candidate. Many real-time implementations check this explicitly and apply the candidate when the solver fails to improve on it. Second, the exact-model assumption enters at exactly one place, . With model error or disturbances, the measured state differs from the predicted one, and the candidate need not be feasible from it. In Figure 1, the recorded values decrease at every step until the tap, then jump from 0.61 to 3.23. Restoring guarantees under such errors is the subject of robust MPC in the next chapter.
The bound in property 3 also gives a quantitative statement that the stick experiment can check. With terminal ingredients and , the closed-loop cost from is 20.15, equal to to solver precision. The next two subsections explain why the bound is tight here.
Constructing Terminal Ingredients for Linear Systems
The conditions of Theorem 1 look abstract, but for a linear system with quadratic stage cost , they can be met with two matrix computations and one scalar.
Terminal controller and cost. Choose a linear terminal controller whose closed-loop matrix has all eigenvalues inside the unit circle, and a quadratic terminal cost . Substituting into the Lyapunov decrease condition gives
The condition holds with equality for every when solves the discrete Lyapunov equation
Because is stable, the solution is unique and equals the series . Hence is exactly the cost of following forever from , provided no constraint is violated along the way. With this choice, the terminal cost is no longer a guess at the tail. It is the cost of one admissible tail.
Any stabilizing works. The natural choice is the gain that makes this tail as cheap as possible, the infinite-horizon linear-quadratic regulator. Its solves the discrete algebraic Riccati equation and its gain is . These formulas are derived by dynamic programming in Finite-Horizon Dynamic Programming. The argument here needs only the Lyapunov equation, which the LQR pair satisfies.
Terminal set. The tail cost is meaningful only where respects the constraints for all future steps. Take an ellipsoid . It is invariant under for every : by the Lyapunov equation,
It remains to choose so that every constraint holds inside . Write each constraint, after substituting , as a pair of half-spaces . For the stick, the rows are with , and with . The largest value of on is , a short Lagrange-multiplier computation that the exercises ask for. Hence the largest admissible level is
With , both conditions of the theorem hold. Invariance and constraint satisfaction hold by construction, and the decrease holds with equality. This is the construction of Chen & Allgöwer (1998), specialized to linear models. For a nonlinear model, the same recipe is applied to the linearization at the equilibrium, with reduced until the neglected nonlinear terms are dominated.
For the stick, the LQR gain is , and the input bound is the binding row, giving . The initial state of the experiments has , well outside , which is why at least nine steps are needed to reach it. Two numerical checks in the build script confirm the construction. Iterating the finite-horizon Riccati recursion from converges to the same to within , and on 2000 random points of , the largest value of is of order 10-15, which is zero to rounding.
Suboptimality Bounds
How does the finite-horizon value compare with the infinite-horizon value of the constrained problem? The answer depends on the terminal ingredients, and the three choices used on the stick give three different answers. Figure 4 plots them.
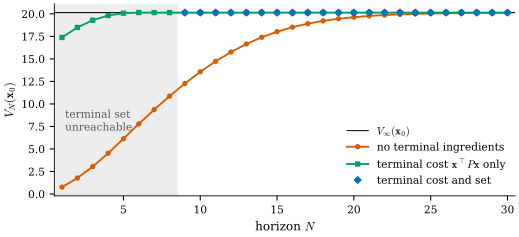
Figure 4:Optimal finite-horizon value from as a function of the horizon, for three terminal choices. Without terminal ingredients the value rises toward from below. With the LQR terminal cost alone it can also lie below . With terminal cost and terminal set the problem is infeasible for (shaded), and equals to solver precision from on.
Without terminal ingredients, is a lower bound. Take the optimal infinite sequence and keep its first commands. They are feasible for the -step problem, and their cost omits only non-negative tail terms. Hence . The same argument shows that is non-decreasing in . On the stick, and , against .
With a terminal cost alone, is neither. The LQR terminal cost is the cost of the unconstrained tail . Outside , that tail violates a constraint, and its cost can be lower than that of any admissible tail. With , the stick gives . An upper bound cannot be obtained without the terminal set.
With terminal cost and terminal set, is an upper bound. Every feasible -step plan, extended by from its terminal state, is an admissible infinite sequence. By the Lyapunov equation, its cost equals the -step objective, because is exactly the cost of the extension. The infinite-horizon problem can choose among more sequences, so on . The bound requires that be at least the cost of following from every point of . A terminal cost that underestimates that tail loses the upper bound.
Deriving the Approximation Error
The interesting question is bounding the approximation error in the third case. It represents the cost of being forced to use beyond the horizon rather than continuing to optimize.
Let denote the infinite-horizon optimal control sequence with corresponding state trajectory where . The infinite-horizon cost is:
Suppose the horizon is long enough that this optimal trajectory has entered the terminal set by step , so that . Then its first commands are feasible for the -step problem, with cost
where approximates the tail cost .
Since is the optimal -horizon cost (which may do better than this particular truncated sequence), we have . The approximation error therefore satisfies:
This bound shows that the approximation error depends on how well the terminal cost approximates the optimal tail cost along the infinite-horizon optimal trajectory, once that trajectory has entered . If , the truncated sequence is infeasible for the -step problem and the bound says nothing.
The stick shows the extreme case. Inside , the LQR law satisfies every constraint, so it is optimal for the constrained problem too, and there. The bound then gives as soon as , which is what Figure 4 shows from on. Combined with property 3 of the theorem,
so the closed-loop cost equals , as measured. On systems where the optimal tail is not linear, is positive and shrinks with at a rate set by how fast optimal trajectories approach .
Summary and Outlook
Receding-horizon control turns a finite-horizon optimizer into feedback by reinitializing it from each measured state and applying only the first planned action. The result is a state-feedback law , defined on the feasible set and evaluated by optimization. On the balancing stick, replanning with a wrong model keeps the stick upright, while under the same plan executed open loop the stick falls within a second.
A short horizon alone guarantees nothing. It can leave an unstable system uncontrolled, lose feasibility, or create a spurious equilibrium near a constraint. A terminal cost, a terminal set, and an invariant local controller connect the truncated problem to the infinite-horizon one. The shifted candidate sequence then proves recursive feasibility, a decreasing value, and a closed-loop cost no larger than . For linear systems, the terminal cost solves a Lyapunov equation, and the terminal set is an ellipsoid whose size follows from the constraints in closed form.
The basic loop leaves several design choices unresolved. How should the same replanning mechanism represent tracking, economic objectives, uncertainty, hybrid decisions, solver failures, and hard real-time deadlines? MPC variants and reliable operation organize those choices. The guarantees here also assumed an exact model, and the robust and stochastic formulations of that chapter address what replaces them.
Exercises
Solution to Exercise 1
With , the objective is , and is fixed, so the minimizer is . The closed loop is , which diverges from every nonzero state.
and . The Lyapunov equation gives . The decrease holds with equality: .
means . The formula gives , and .
Solution to Exercise 2
The objective is . Setting its gradient in to zero gives , which is . Without constraints, its value is by the Riccati equation, the unconstrained infinite-horizon cost. This is the green curve at . From , the unconstrained LQR tail exceeds the command bound, so it is cheaper than every admissible tail, and the value 17.38 lies below the constrained .
Solution to Exercise 3
The maximum of a linear function over the ellipsoid is attained on its boundary. Stationarity of gives . Substituting into gives , and the value is . The half-space contains the ellipsoid exactly when this value is at most , that is, when . By symmetry, the same condition covers . Taking the minimum over all rows gives .
Solution to Exercise 4
The closed loop settles at , rad, with a constant command close to rad/s, which cancels the gravitational acceleration. The last plan holds the stick nearly still, and its predicted angle approaches the limit at the end of the horizon. Within five steps, pushing the stick back costs more command effort than it saves in angle cost, so the plan that holds the state is optimal, and applying its first command reproduces the same state. With , the same state falls away. With , the stick still parks, near rad. is the smallest horizon that returns it upright within 200 steps, with closed-loop cost 34.1, and lowers that cost to 24.1.
Solution to Exercise 5
The proof assumes . The tap violates that assumption by 0.5 rad/s in one step, and jumps from 0.61 to 3.23. The shorter stick violates it by a small amount at every step, so the decrease inequality can fail by a margin even where keeps decreasing. The shifted candidate is built from the predicted state, so it need not be feasible from the measured one. Recursive feasibility is no longer guaranteed, and for a short enough stick it fails. The threshold depends on the tap and the initial state, which is why robust MPC tightens the constraints by bounds on the prediction error.
Solution to Exercise 6
The terminal level becomes the minimum over three rows. For the rate row,
and give .
For the angle row the value is 8.99, and for the input row 4.02. The input
bound still binds, so and do not change, although the
rate bound comes close. The function terminal_level performs the same
computation. The feasible sets are cut by the horizontal lines
. Where the rate bound becomes active along the optimal
predicted path, the first command can differ from the saturated linear law, so
measure the gap rather than assume it.
Computational Sources
The model, the MPC subproblem, and the checks are in one module, and the figures and numbers are produced by one script:
Run uv run python scripts/build_receding_horizon_artifacts.py from the
repository root to regenerate the four figures and the metrics, in about one
minute. Normal book builds read the saved figures. The tests in
tests/test_receding_horizon.py check the Lyapunov equation, the terminal
level, the shifted-candidate inequality, recursive feasibility, and the
bounds on on short runs.
Self-checks
Solution to Exercise 7
Only the first control (or first short control block) is applied. The state is measured again and the horizon is shifted before re-optimizing.
Solution to Exercise 8
The terminal cost approximates value beyond the horizon; the terminal constraint can keep the endpoint in a region from which a known controller remains feasible and stable.
Solution to Exercise 9
The newly measured state contains the accumulated effect of disturbances and model error. Reinitializing the optimization from that state changes the planned controls accordingly.
- Bemporad, A., Morari, M., Dua, V., & Pistikopoulos, E. N. (2002). The explicit linear quadratic regulator for constrained systems. Automatica, 38(1), 3–20. 10.1016/S0005-1098(01)00174-1
- Grüne, L., & Pannek, J. (2017). Nonlinear Model Predictive Control: Theory and Algorithms (2nd ed.). Springer. 10.1007/978-3-319-46024-6
- Mayne, D. Q., Rawlings, J. B., Rao, C. V., & Scokaert, P. O. M. (2000). Constrained model predictive control: Stability and optimality. Automatica, 36(6), 789–814. 10.1016/S0005-1098(99)00214-9
- Rawlings, J. B., Mayne, D. Q., & Diehl, M. M. (2017). Model Predictive Control: Theory, Computation, and Design (2nd ed.). Nob Hill Publishing.
- Chen, H., & Allgöwer, F. (1998). A quasi-infinite horizon nonlinear model predictive control scheme with guaranteed stability. Automatica, 34(10), 1205–1217. 10.1016/S0005-1098(98)00073-9